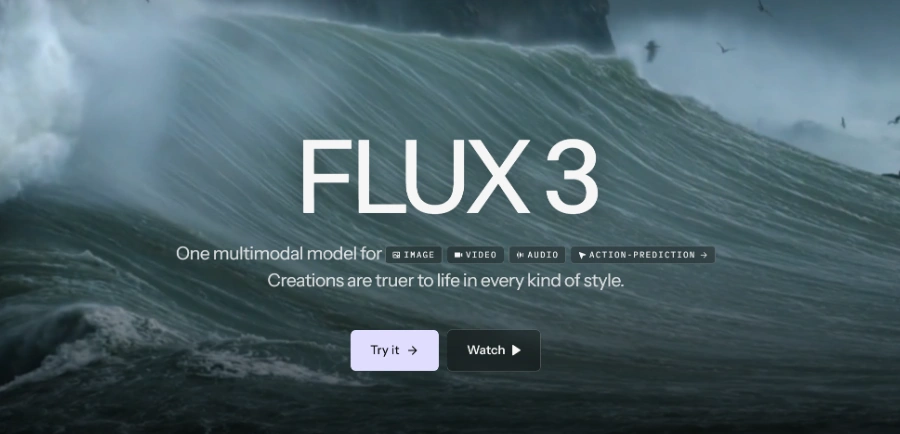
FLUX 3
FLUX 3 is a multimodal foundation model for video, image, and audio generation, offering action prediction and real-world visual intelligence.
Related Categories
Relevant Reads
Related AI Tools
Motiofy
Motiofy is an AI video generator that transforms still images into dynamic video clips for product listings, ads, and social media.
VlogMe AI
VlogMe AI is an AI video generator with an AI Director, planning and creating complete videos using multiple advanced AI models for diverse tasks.
LTX 2.5
LTX 2.5 is an all-in-one creative studio for AI video production, designed for creative teams, marketers, and filmmakers.
Senzia
Senzia is a free online AI video, image, and audio generator that transforms ideas, text, photos, or audio into cinema-grade visuals without editing skills.
Imagine Image 2.0
Imagine Image 2.0 is Grok's advanced image generation model, offering improved quality and prompt adherence for Grok subscribers.
Revid
Revid is an online AI video generator that transforms ideas, text, images, or references into high-quality videos for various content creation needs.
Freebeat AI Mobile
AI-powered mobile video generator for creating stunning visuals with a few taps.
Stivio ai
Stivio ai is an online AI video generator that animates photos into HD MP4 clips using text prompts for motion.
FLUX 3 jointly learns from images, videos, and audio within a single architecture to build a comprehensive representation of the world.
All video outputs generated by FLUX 3 come with integrated, native audio generation, associating sounds with physical events.
The model can create diverse videos up to 20 seconds in length directly from pure text prompts.
FLUX 3 can generate videos by continuing from a starting image (animation) or by using images as visual references.
FLUX 3's world understanding extends to action prediction, either natively integrated or as a backbone for finetuning specialized action models for robotics.
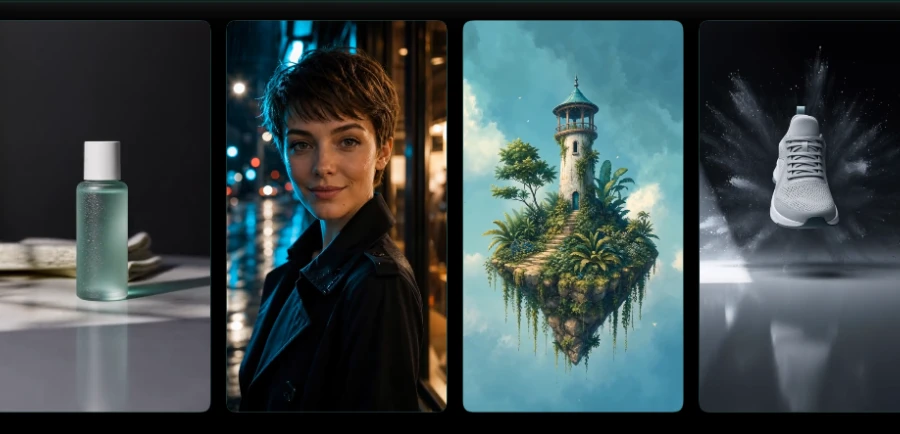
FLUX 3 can synthesize and edit images across a wide variety of styles, aspect ratios, and resolutions, including high-accuracy text rendering in multiple languages.
The model supports agentic chaining of individual clips into longer, multi-shot sequences, with visual references helping to ensure character consistency across scenes.
FLUX 3 handles a broad range of visual styles from candid camcorder footage to animation and cinematics, and supports multilingual dialogue in video outputs.
Detailed Pricing Info
- Unified multimodal learning from video, image, and audio within a single architecture for a comprehensive world representation.
- Generates video with native, integrated audio, enhancing realism and causal relationships between mechanical phenomena and acoustics.
- Capable of diverse video generation methods including text-to-video, image-to-video, video-to-video, and keyframe-to-video.
- Includes advanced action prediction capabilities, making it suitable for physical AI and robotics applications.
- Demonstrates strong performance against leading competitor models in early evaluations, preferred in up to 93% of comparisons.
- Excels in capturing human facial expressions, associating sounds with physical events, and maintaining character consistency across long, multi-shot sequences.
- The model is currently in 'Early Access' and 'still in development,' meaning results are preliminary and subject to further improvements.
- Specific pricing for FLUX 3 Video generation is not explicitly detailed on the provided pricing page, only for FLUX 3 Image.
What is FLUX 3?
What are the key capabilities of FLUX 3 Video?
Does FLUX 3 support image generation?
What is the pricing model for FLUX 3?
Related Topics
Write a Review
Community Feedback (0)
Ready to try FLUX 3?
Motiofy
Motiofy is an AI video generator that transforms still images into dynamic video clips for product listings, ads, and social media.
VlogMe AI
VlogMe AI is an AI video generator with an AI Director, planning and creating complete videos using multiple advanced AI models for diverse tasks.
LTX 2.5
LTX 2.5 is an all-in-one creative studio for AI video production, designed for creative teams, marketers, and filmmakers.
Senzia
Senzia is a free online AI video, image, and audio generator that transforms ideas, text, photos, or audio into cinema-grade visuals without editing skills.
Imagine Image 2.0
Imagine Image 2.0 is Grok's advanced image generation model, offering improved quality and prompt adherence for Grok subscribers.
Revid
Revid is an online AI video generator that transforms ideas, text, images, or references into high-quality videos for various content creation needs.
Freebeat AI Mobile
AI-powered mobile video generator for creating stunning visuals with a few taps.
Stivio ai
Stivio ai is an online AI video generator that animates photos into HD MP4 clips using text prompts for motion.